Keep AI Costs Under Control at Scale
Most organizations lack visibility into AI inference and token spending across teams, models, and workflows — leading to runaway costs and missed optimization.
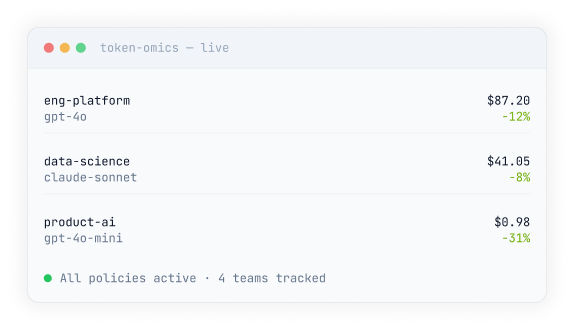

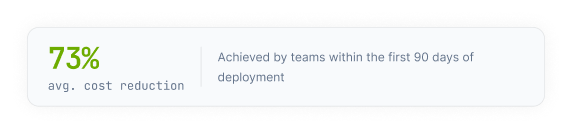

Unified Visibility and Control
Token-omics serves as a single source of truth for token consumption — giving every stakeholder the clarity they need to act.
Cut Costs Immediately
Identify and eliminate wasteful token usage across teams from day one.
Set Smart Budgets
Define per-team, per-model, and per-workflow budget policies with automated enforcement.
Optimize Model Choice
Route workloads to the most cost-effective model without sacrificing quality.
Deep Insights
Granular analytics across every dimension: team, model, prompt type, and time.
Governance at Scale
Centralize compliance, audit trails, and access controls for AI usage.
Future-Proof Spending
Forecast AI costs as models and usage evolve with confidence.
Distributed AI Spending Creates a Blind Spot
As AI adoption spreads across engineering, product, data, and research — token spend fragments into dozens of invisible streams with no central tracking.
Across engineering, product, data, and research with no central tracking or visibility into usage patterns.
Redundant calls, unused models, inefficient prompts — invisible until Token-omics exposes them.
Measurable ROI, fast
Most teams break even in under one quarter
Sustained reduction after initial optimization
Finance
Forecast AI spend with confidence. Real-time actuals vs. budget, chargebacks, and trend projections.
Engineering
See per-service token usage. Catch regressions before they hit the budget. Optimize prompts with data.
Compliance
Full audit trail. Model usage logs, access records, and policy enforcement history on demand.
Product
Understand which features drive token cost. Ship AI features with cost-awareness built in.
Six Core Capabilities for Full Control
Route All Calls
Point your AI applications through token-omics instead of directly to model providers.
Understand the Request
Analyze intent, complexity, token requirements, and required capabilities before selecting a model.
Apply Guardrails
Enforce organizational policies for models, budgets, data, rate limits, and compliance.
Route Intelligently
Automatically select the most cost-efficient model capable of handling the request.
Measure & Track
Log every request, token, model, cost, latency, and routing decision.
Gain Insights
Understand where AI spend is going, identify waste, forecast costs, and continuously optimize.
Start controlling your AI spend today
Schedule a demo and see Token-omics running against your actual AI workloads within 24 hours.
Control Every Request. Optimize Every Token.
token-omics doesn't just track AI spending. It helps organizations decide which models can be used, how requests should be handled, and how much each workflow should cost.
AI Guardrails
Enforce model access policies, budget limits, token caps, and usage rules before requests reach AI providers.
Complexity-Based Routing
Match each request to an appropriate model based on complexity, capability, cost, and latency requirements.